UNSW NLP Group
Interested in joining? Email us with [Expression of Interest: Type] in the subject, where Type is one of:
Recent News
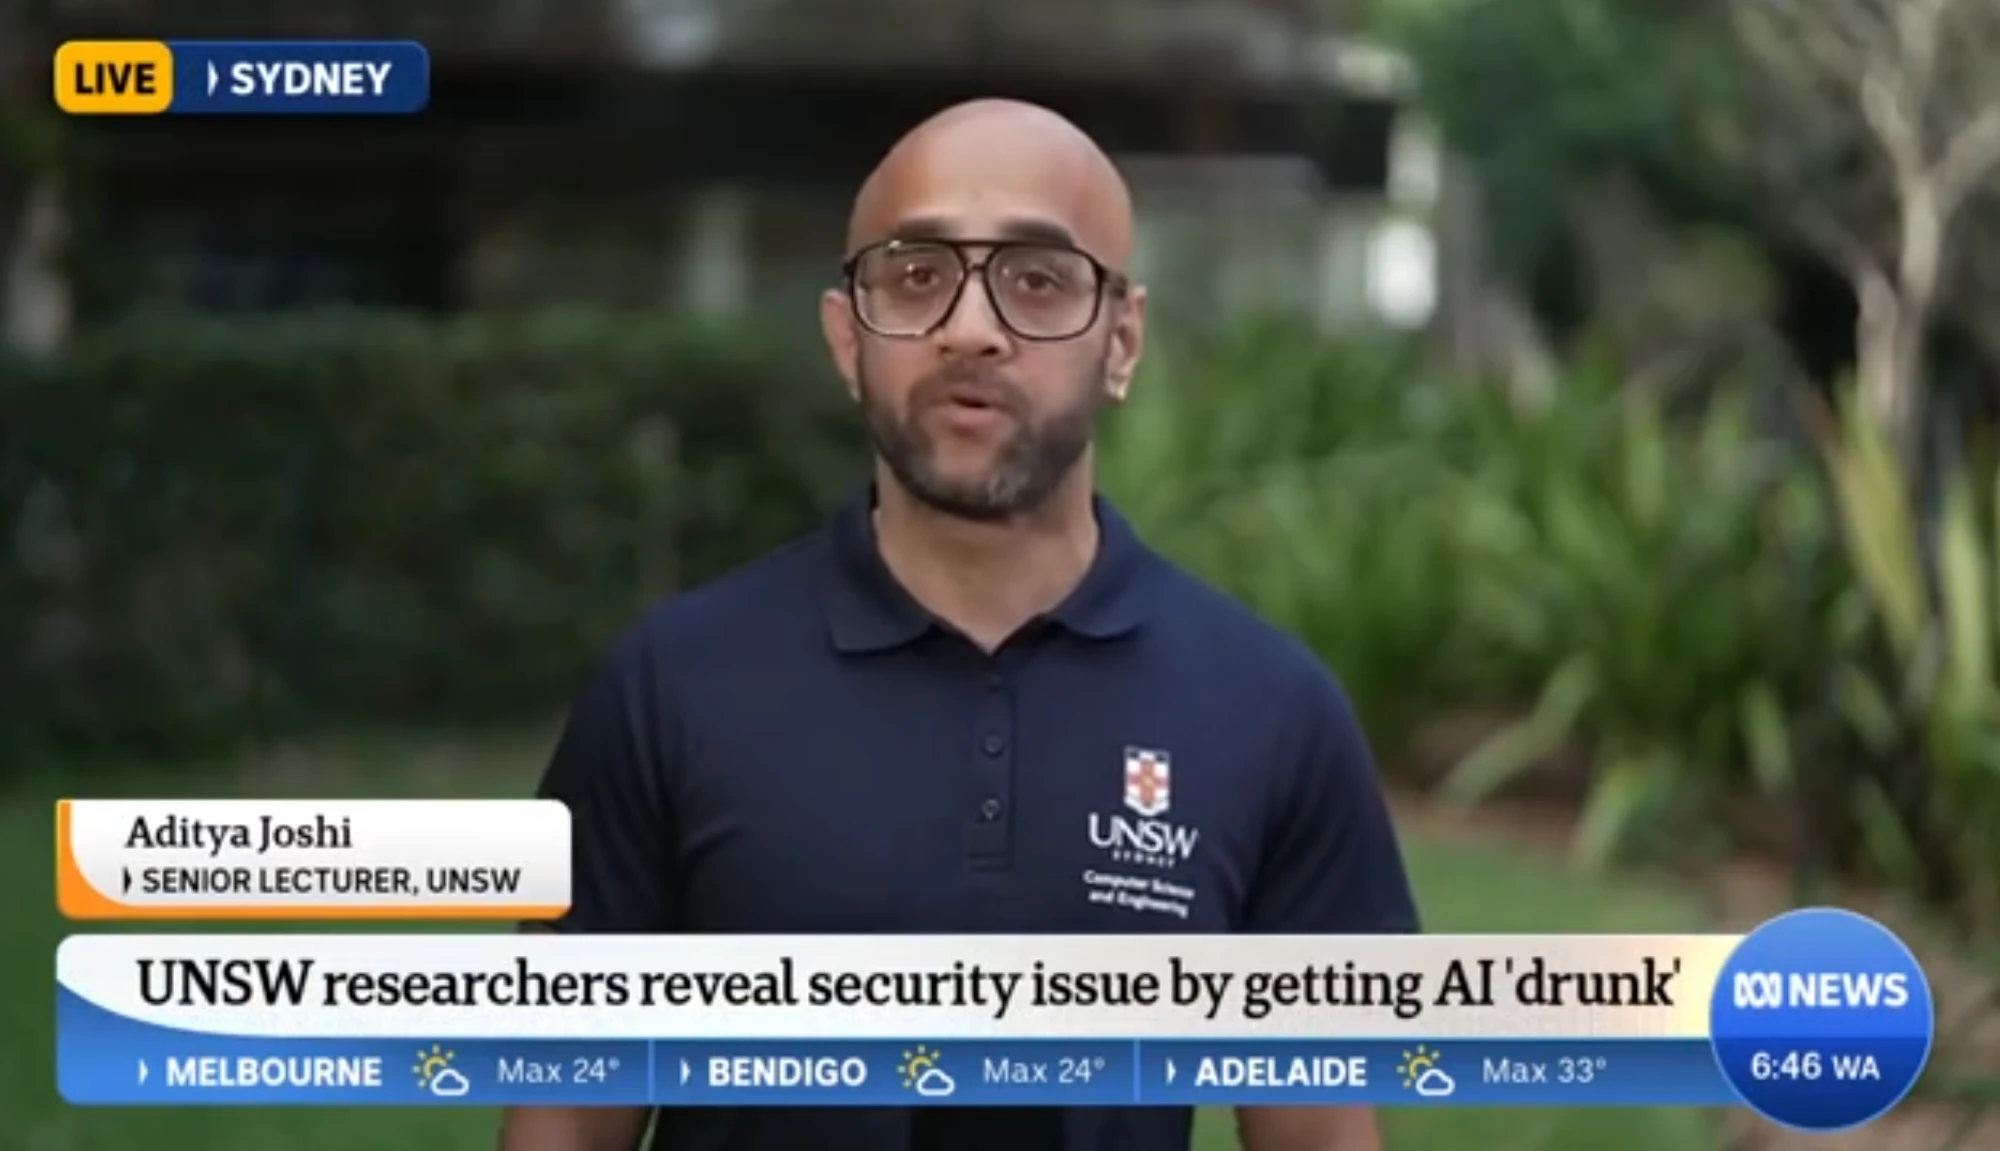
Our research on getting AI “drunk” to expose new security risks in chatbots was featured on ABC News, news.com.au and the UNSW Newsroom | |
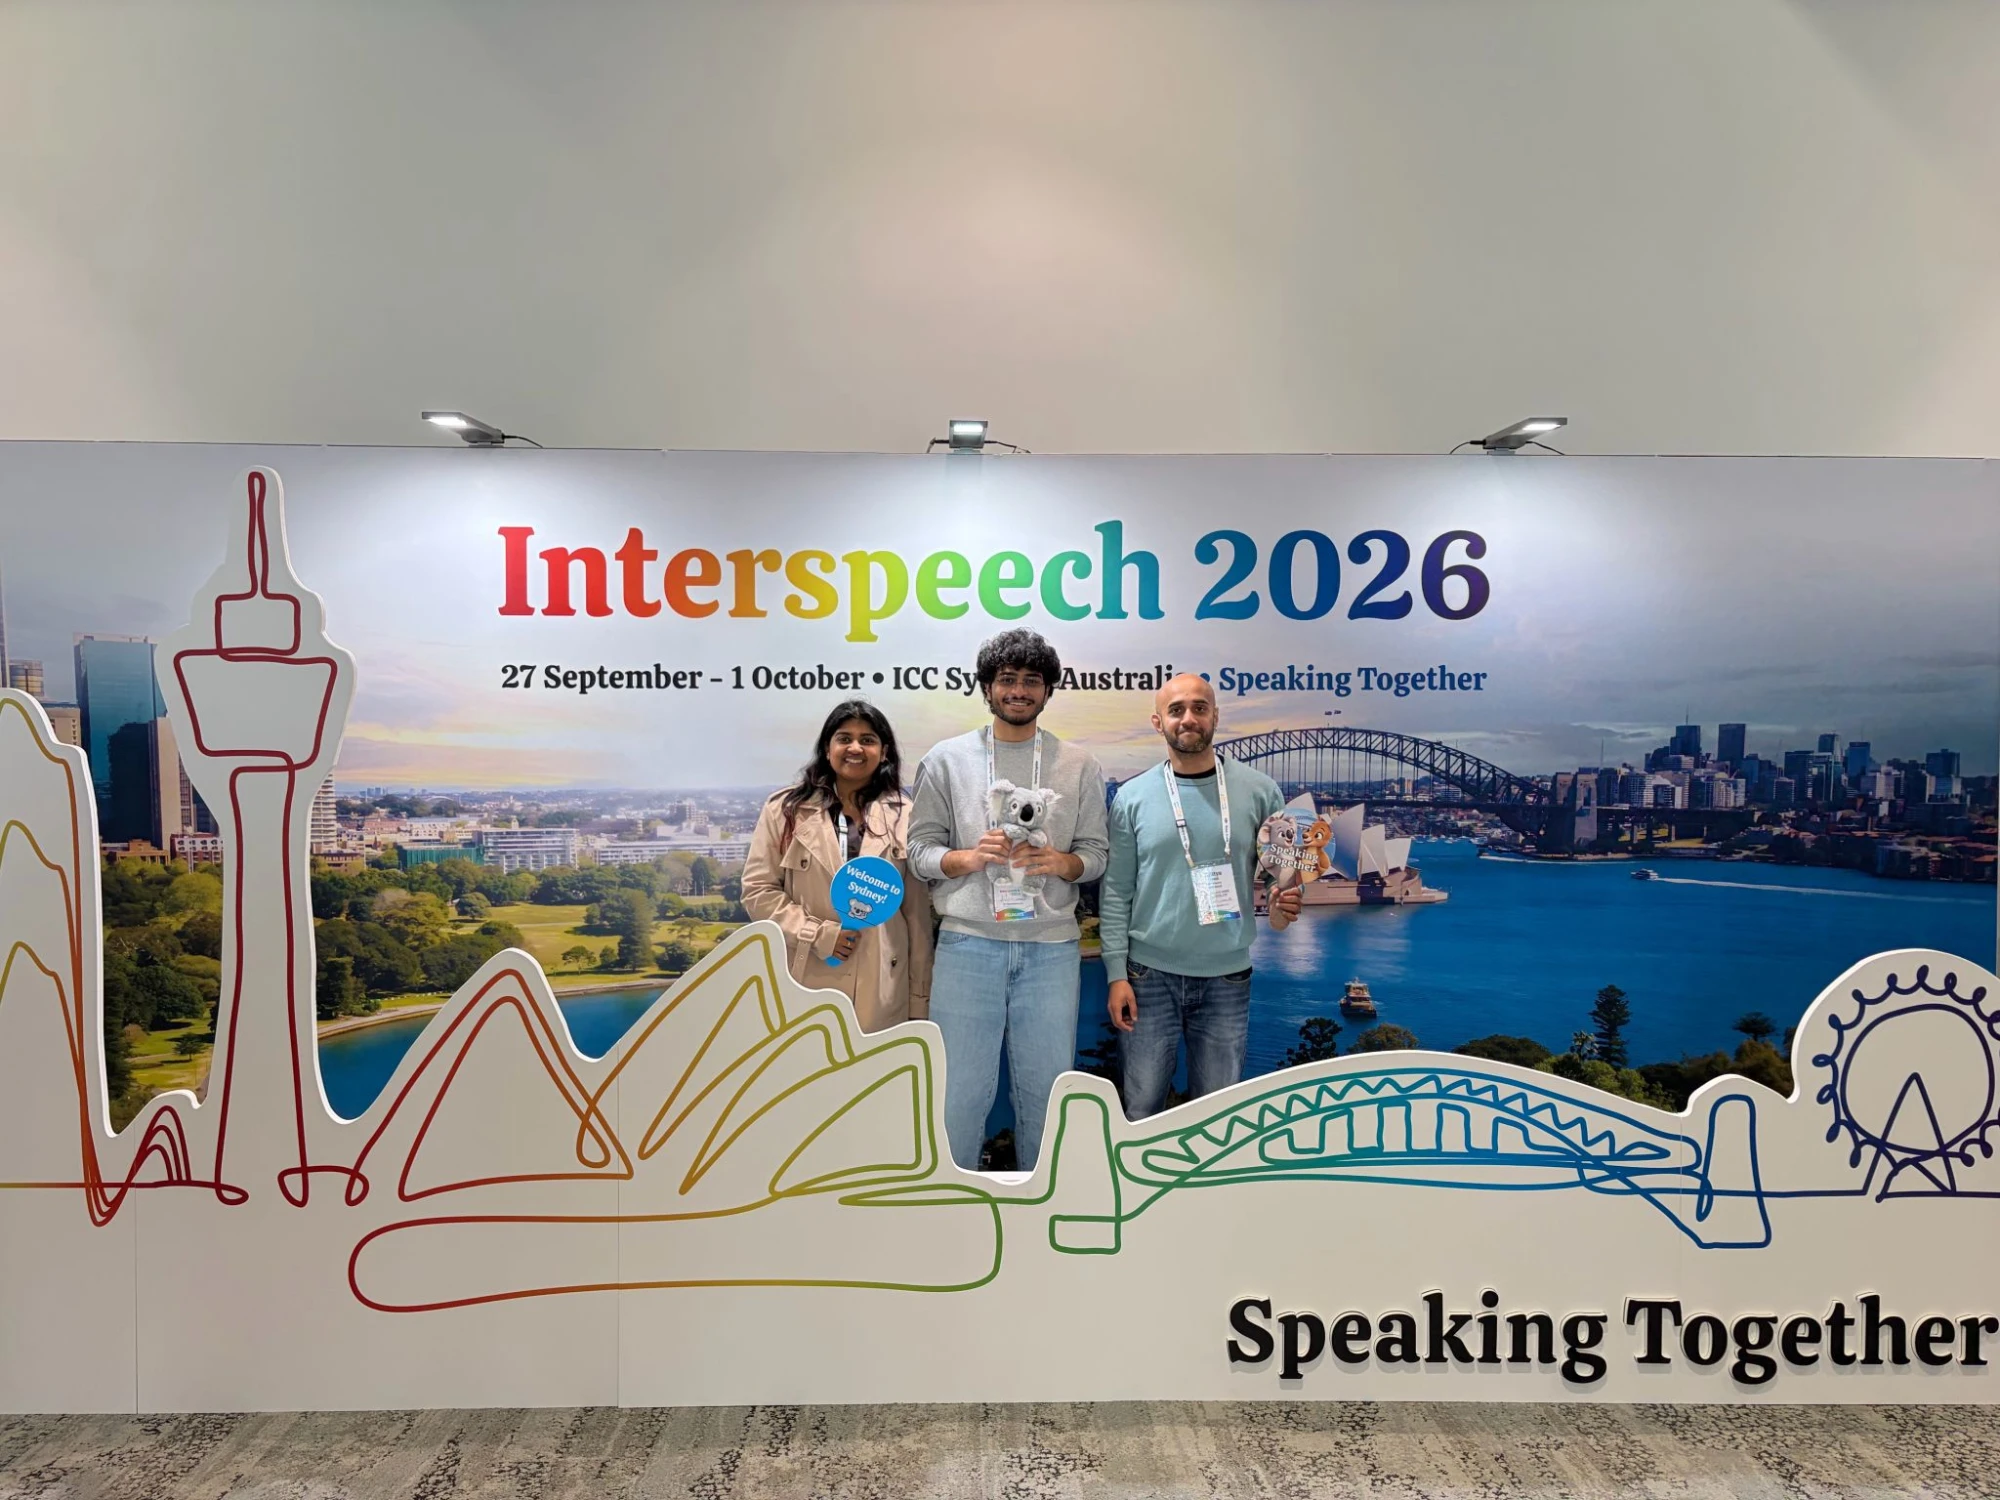
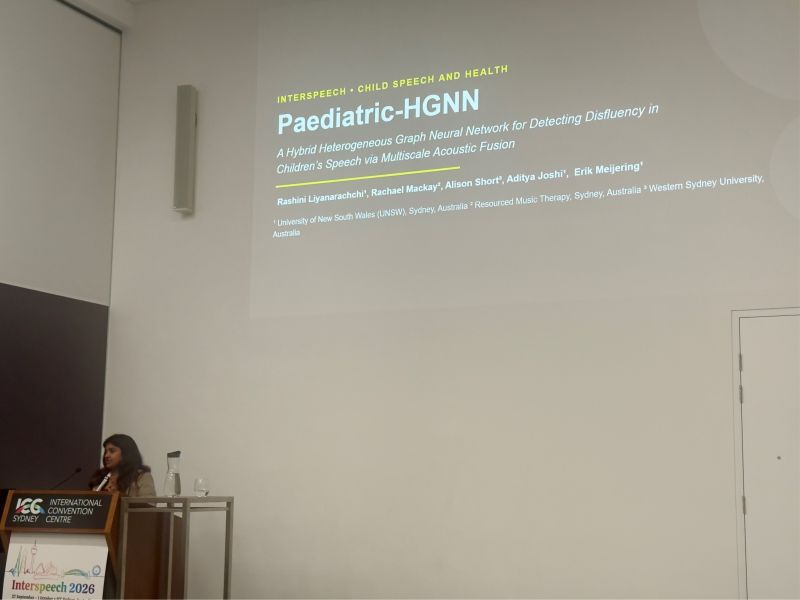
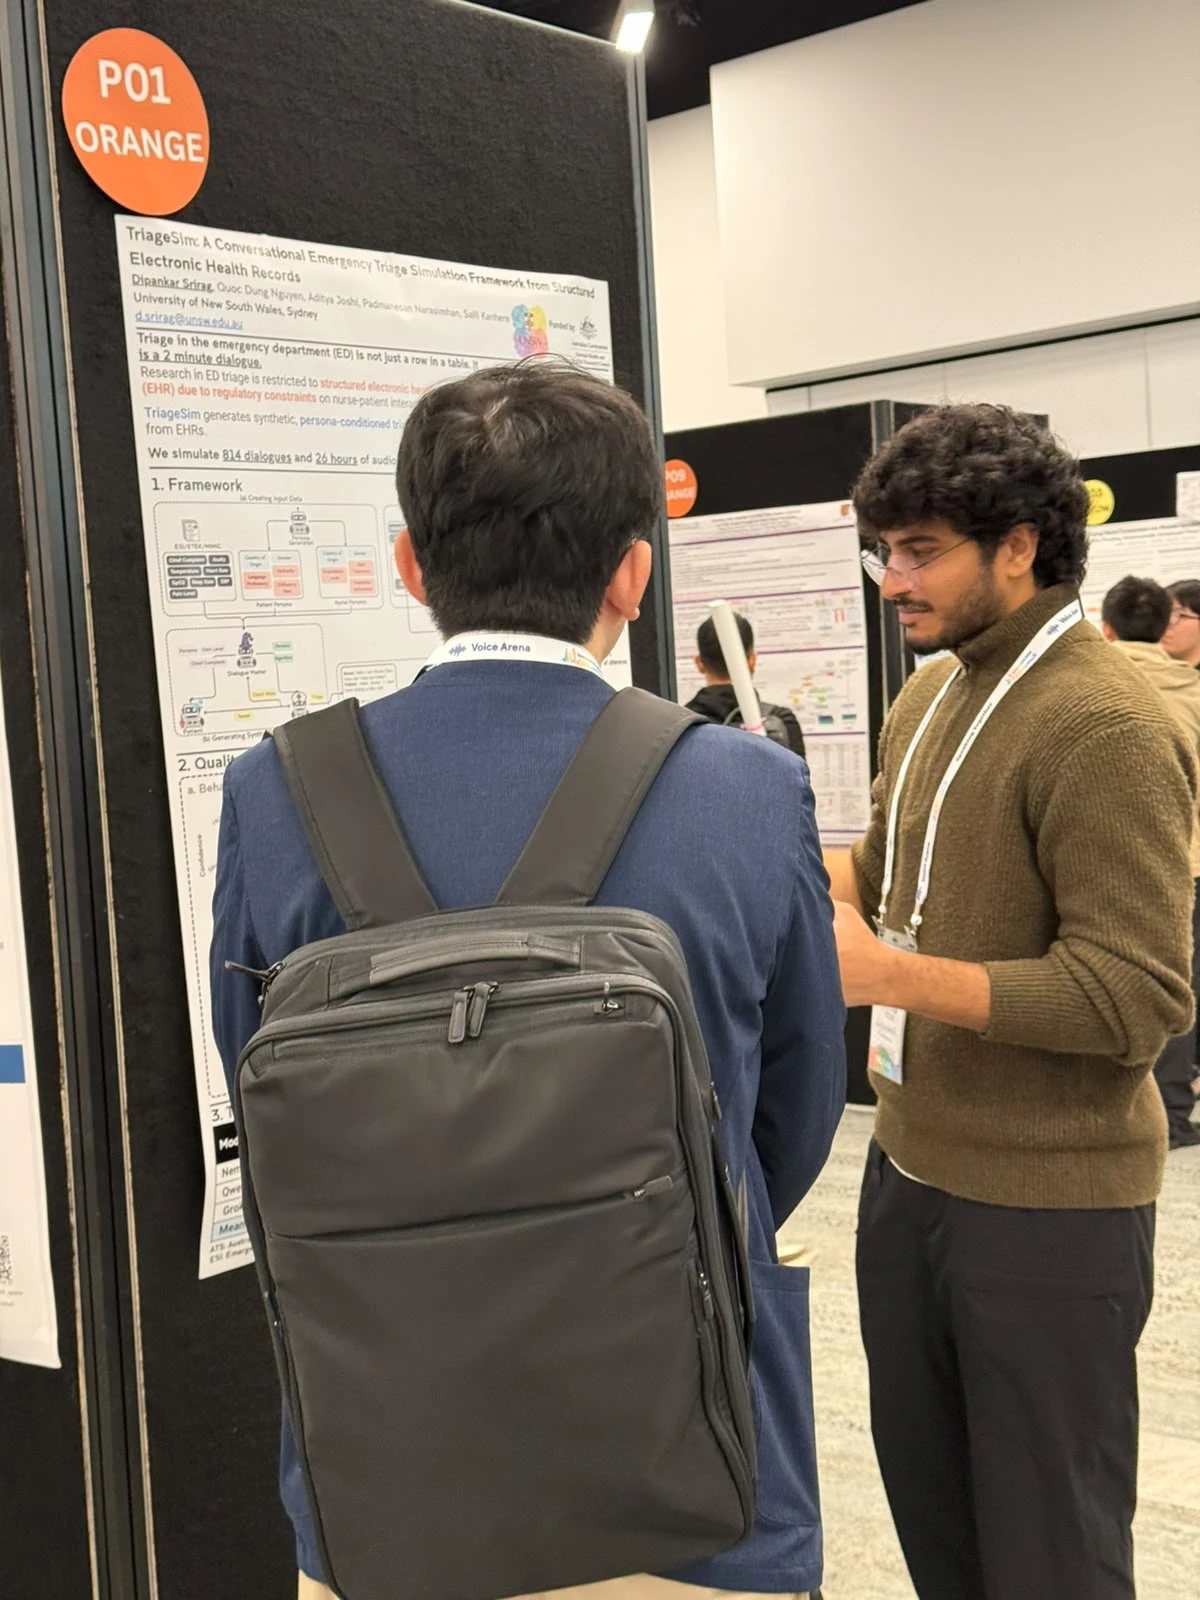
Two papers accepted at Interspeech 2026 (Main): stuttering detection in paediatric speech and TriageSim. | |
Far Out, evaluating language models on slang in Australian and Indian English, accepted to VarDial @ EACL 2026. | |
Amrita’s system paper on Arabic medical text classification accepted to AbjadNLP @ EACL 2026. | |
TriageSim, a conversational emergency triage simulation framework from electronic health records, released as a Python package. | |
Charles’s paper on evaluating LLMs for masked sentence prediction accepted to IJCNLP-AACL 2025. | |
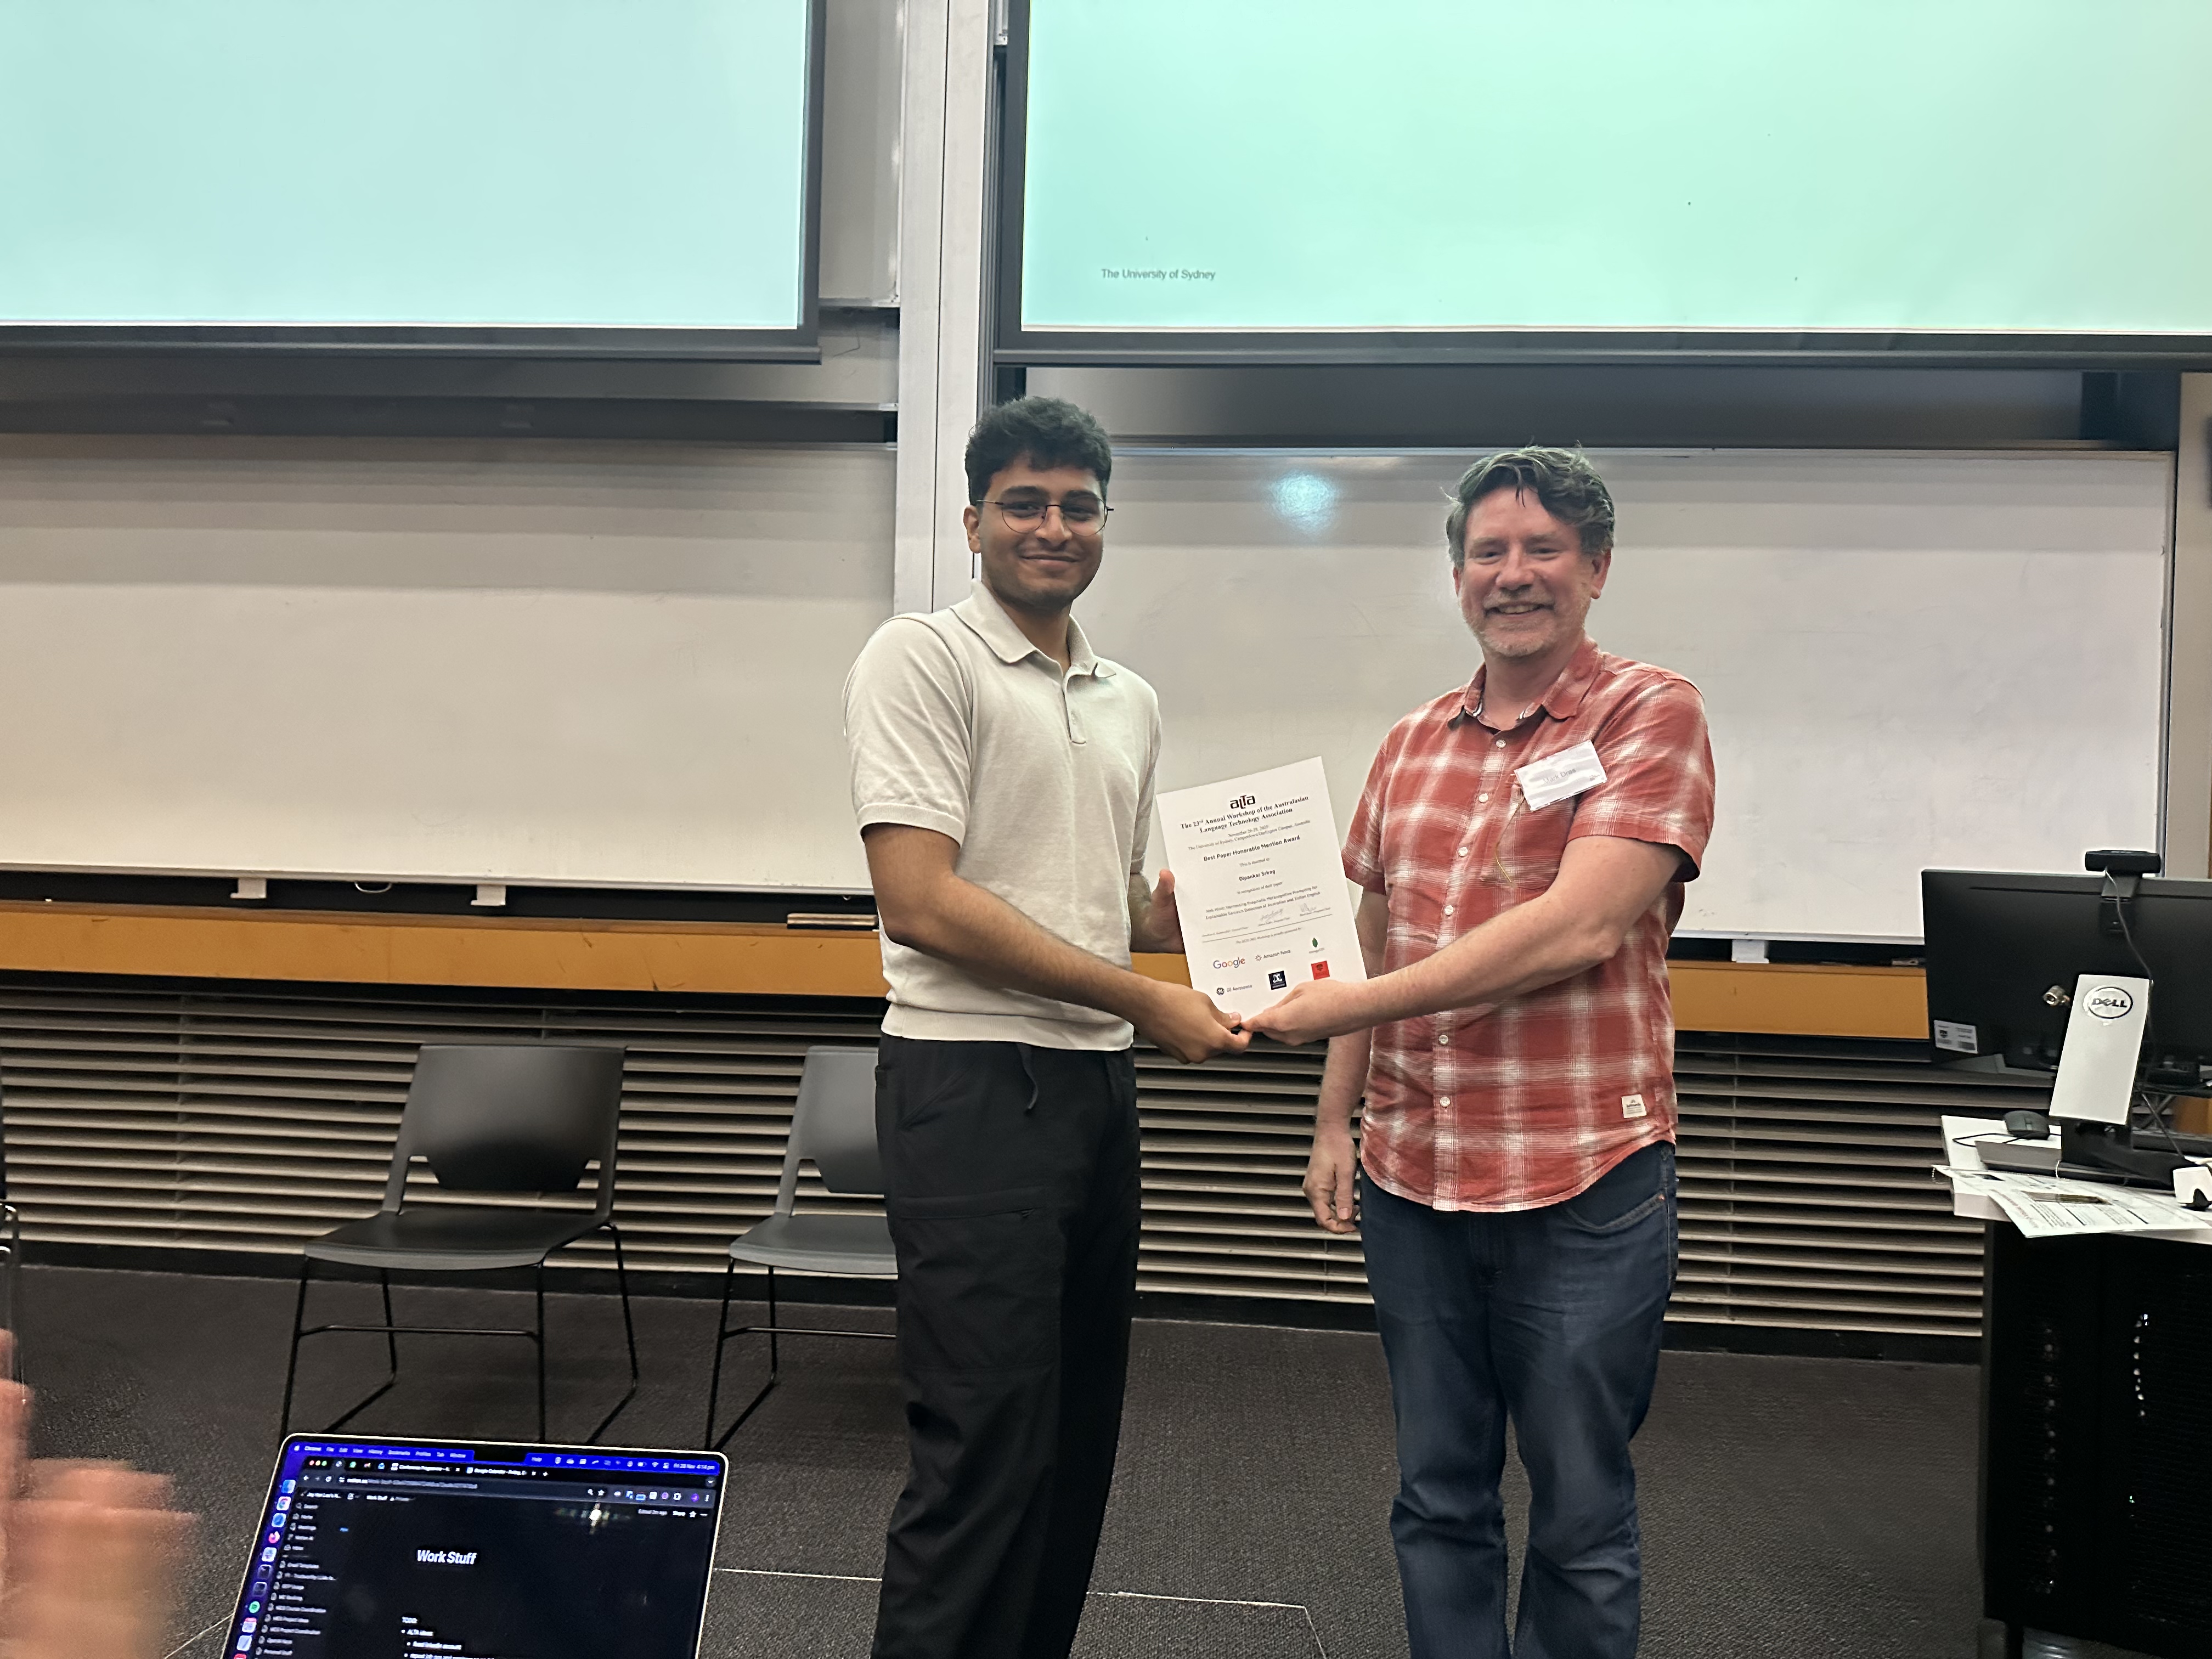
Nek Minit received the Best Paper Honorable Mention at ALTA 2025, co-organised by Aditya. | |
Amrita’s survey on classification tasks for legal contracts accepted to Artificial Intelligence Review. | |
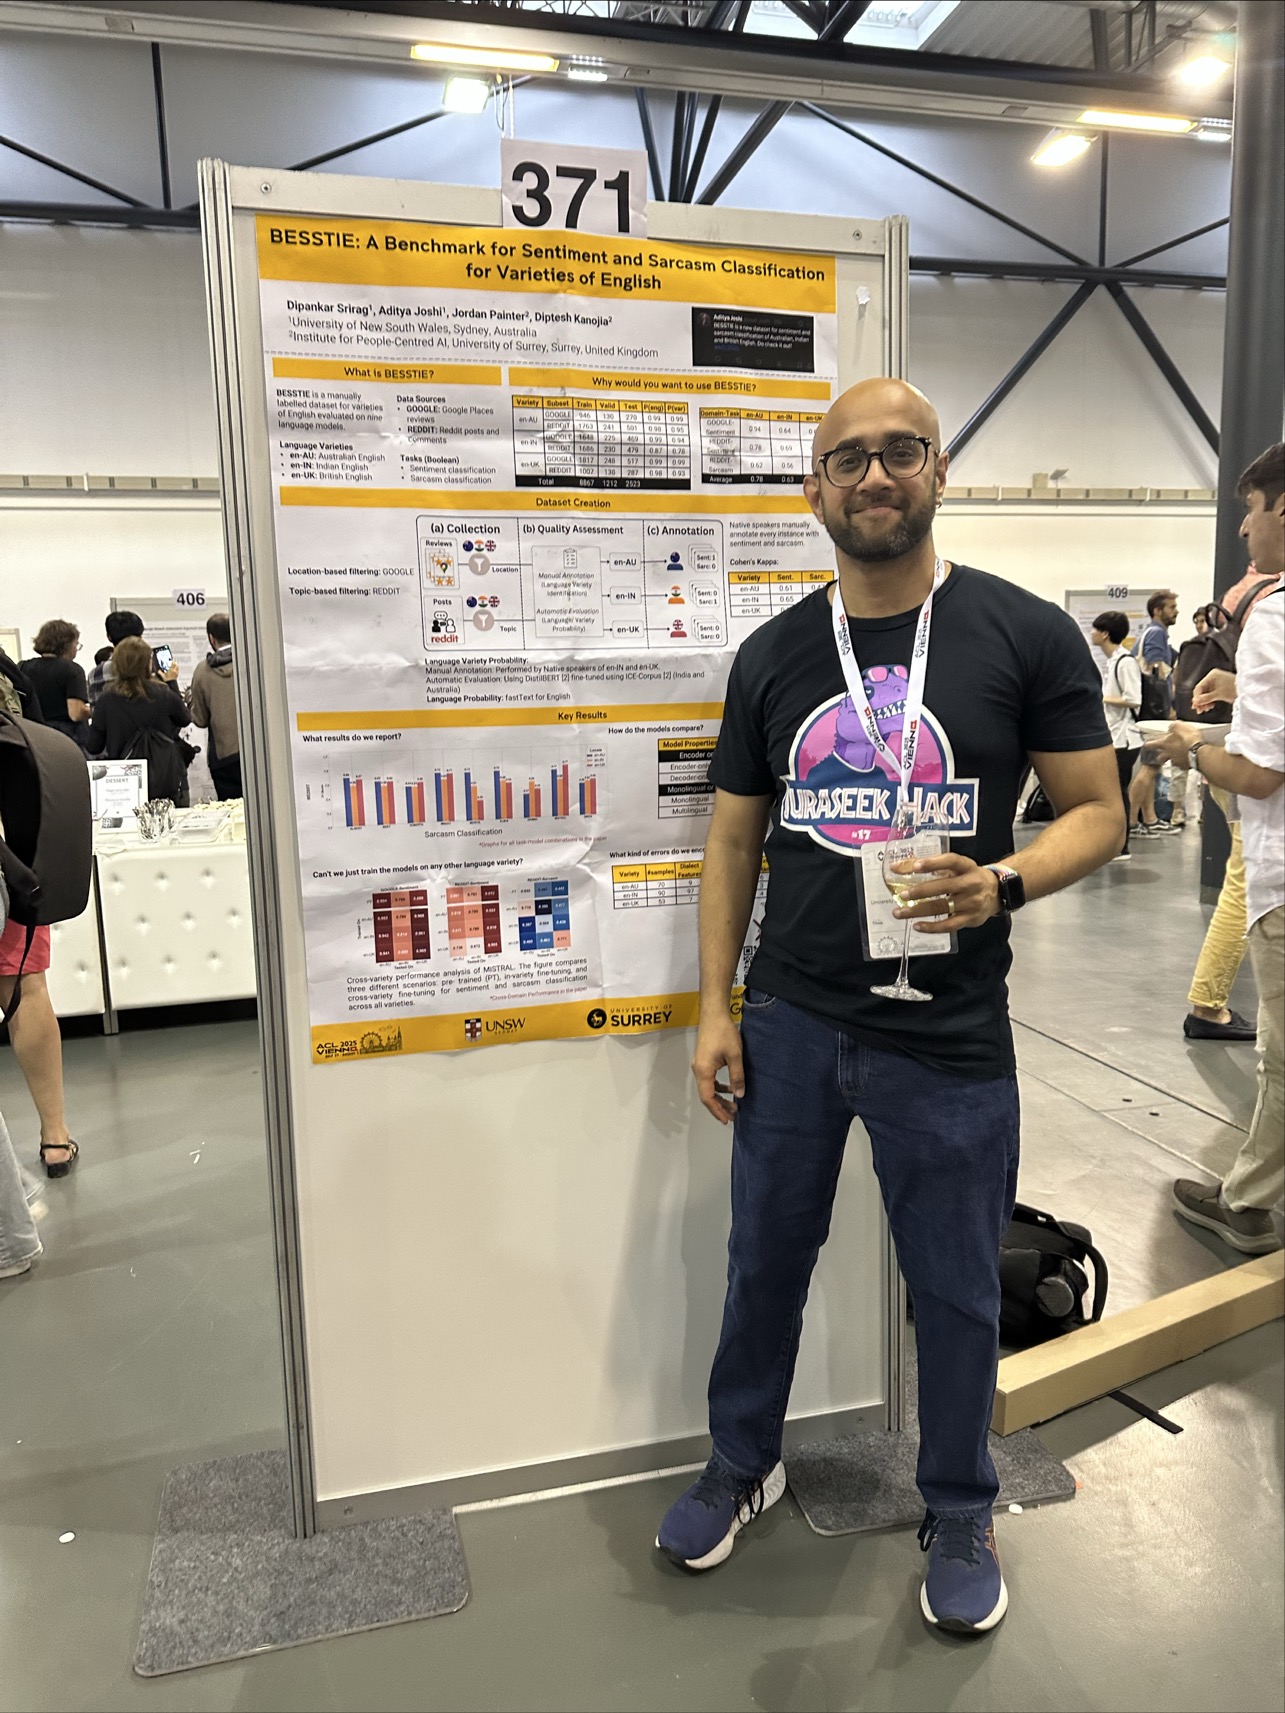
BESSTIE, a benchmark for sentiment and sarcasm across varieties of English, accepted to Findings of ACL 2025. Dataset on HuggingFace. | |
RACCOON, retrieval-augmented geocoding for news articles, accepted to TheWebConf 2025. |
Selected Publications
BibTeX
@article{10.1145/3712060,
author = {Joshi, Aditya and Dabre, Raj and Kanojia, Diptesh and Li, Zhuang and Zhan, Haolan and Haffari, Gholamreza and Dippold, Doris},
title = {Natural Language Processing for Dialects of a Language: A Survey},
year = {2025},
issue_date = {June 2025},
publisher = {Association for Computing Machinery},
address = {New York, NY, USA},
volume = {57},
number = {6},
issn = {0360-0300},
url = {https://doi.org/10.1145/3712060},
doi = {10.1145/3712060},
abstract = {State-of-the-art natural language processing (NLP) models are trained on massive training corpora, and report a superlative performance on evaluation datasets. This survey delves into an important attribute of these datasets: the dialect of a language. Motivated by the performance degradation of NLP models for dialectal datasets and its implications for the equity of language technologies, we survey past research in NLP for dialects in terms of datasets, and approaches. We describe a wide range of NLP tasks in terms of two categories: natural language understanding (NLU) (for tasks such as dialect classification, sentiment analysis, parsing, and NLU benchmarks) and natural language generation (NLG) (for summarisation, machine translation, and dialogue systems). The survey is also broad in its coverage of languages which include English, Arabic, German, among others. We observe that past work in NLP concerning dialects goes deeper than mere dialect classification, and extends to several NLU and NLG tasks. For these tasks, we describe classical machine learning using statistical models, along with the recent deep learning-based approaches based on pre-trained language models. We expect that this survey will be useful to NLP researchers interested in building equitable language technologies by rethinking LLM benchmarks and model architectures.},
journal = {ACM Comput. Surv.},
month = feb,
articleno = {149},
numpages = {37},
keywords = {NLP, dialects, natural language processing, linguistic diversity, large language models, inclusion}
}
Copied!BibTeX
@misc{srirag2026triagedischargesurveynlp,
    title={From Triage to Discharge: A Survey of NLP Tasks, Methods, and Open Challenges in the Emergency Department},
    author={Dipankar Srirag and Aditya Joshi and Salil Kanhere and Padmanesan Narasimhan},
    year={2026},
    eprint={2608.23627},
    archivePrefix={arXiv},
    primaryClass={cs.CL},
    url={https://arxiv.org/abs/2608.23627},
}
Copied!BibTeX
@misc{doan2026benchmarkconstructionevaluationframework,
    title={A Benchmark Construction and Evaluation Framework for Specialist Domains: Case Study on Defense-related Documents},
    author={Bao Gia Doan and Aditya Joshi and Pantelis Elinas and Aarya Bodhankar and Oscar Leslie and Tom Marchant and Flora Salim},
    year={2026},
    eprint={2604.17943},
    archivePrefix={arXiv},
    primaryClass={cs.CL},
    url={https://arxiv.org/abs/2604.17943},
}
Copied!BibTeX
@inproceedings{liyanarachchi26_interspeech,
  title     = {{Paediatric-HGNN: A Hybrid Heterogeneous Graph Neural Network for Detecting Disfluency in Children's Speech via Multiscale Acoustic Fusion}},
  author    = {Rashini Liyanarachchi and Rachael Mackay and Alison Short and Aditya Joshi and Erik Meijering},
  year      = {2026},
  booktitle = {{Interspeech 2026}},
  pages     = {5600--5604},
  doi       = {10.21437/Interspeech.2026-1131},
  issn      = {2958-1796},
}
Copied!BibTeX
@misc{shetty2026vinoveritasvulnerabilitiesexamining,
    title={In Vino Veritas and Vulnerabilities: Examining LLM Safety via Drunk Language Inducement},
    author={Anudeex Shetty and Aditya Joshi and Salil S. Kanhere},
    year={2026},
    eprint={2601.22169},
    archivePrefix={arXiv},
    primaryClass={cs.CL},
    url={https://arxiv.org/abs/2601.22169},
}
Copied!Funding
Group at Conferences
Group Outings